Product
Learned or governed? Both.
The control layer for recommendations: understand your audience, test what works, see why recommendations happen and control what gets shown.
One request
GET /v1/recommendations ?user_id=user-123 &context_id=101 &limit=5 Authorization: Bearer NSL_KEY_...One API · whatever model is underneath
What came back
request_id c7f0d2bb- 01Waterproof shellaffinity0.94
- 02Merino base layercomplement0.88
- 03Peak District guideboost ×1.40.81
- 04Camp stovepopularity0.74
- 05Trail running shoessession0.69
processing_time_ms 182 · has_more false
Understand your audience
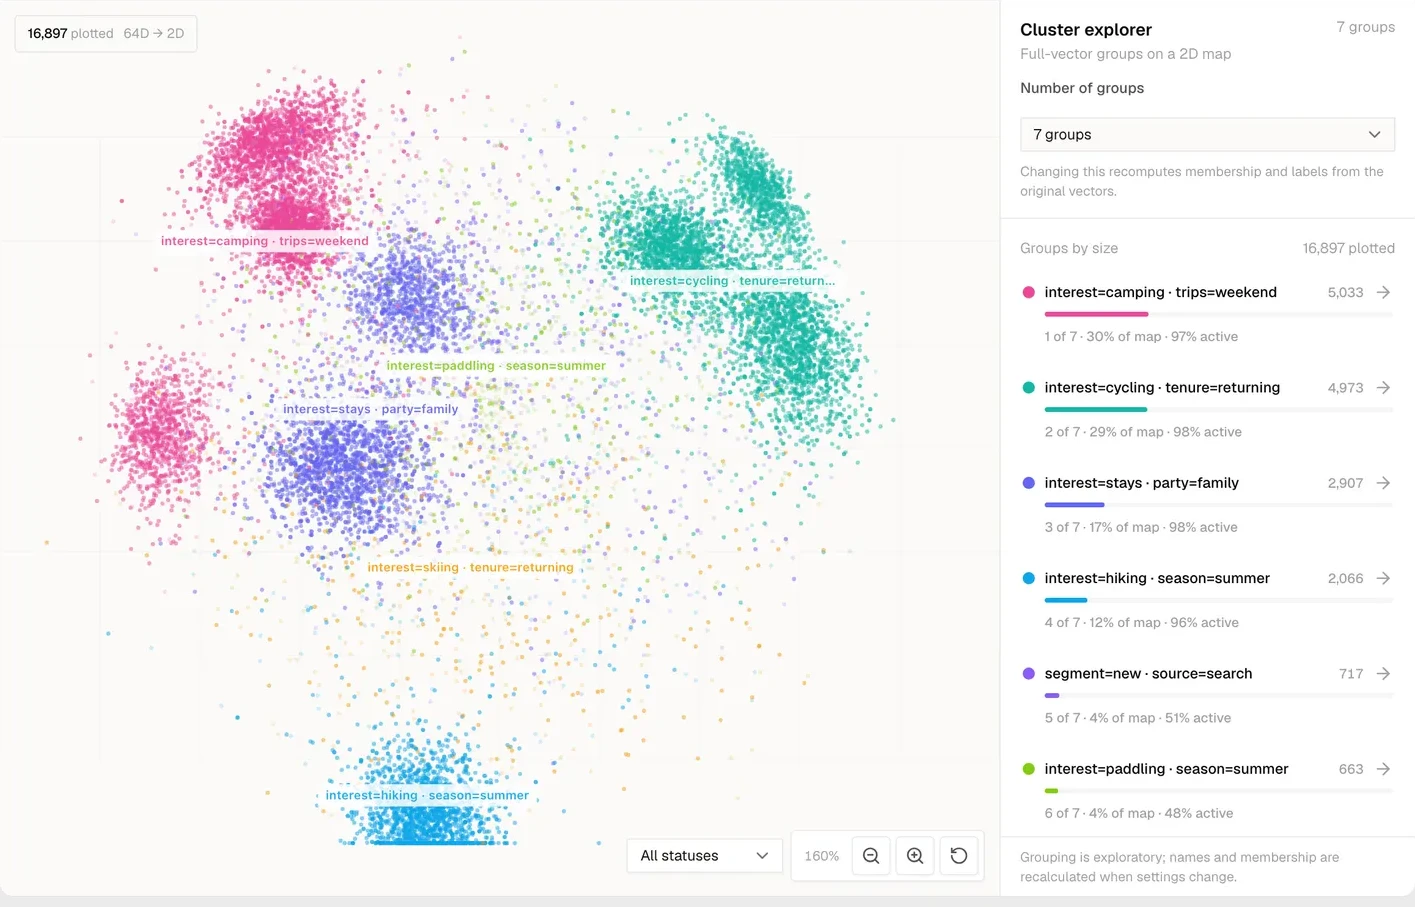
A living map of users, content and interests, with the behavioural communities in your data found rather than defined by hand - and each person's profile kept current as their interests move.
Test what works
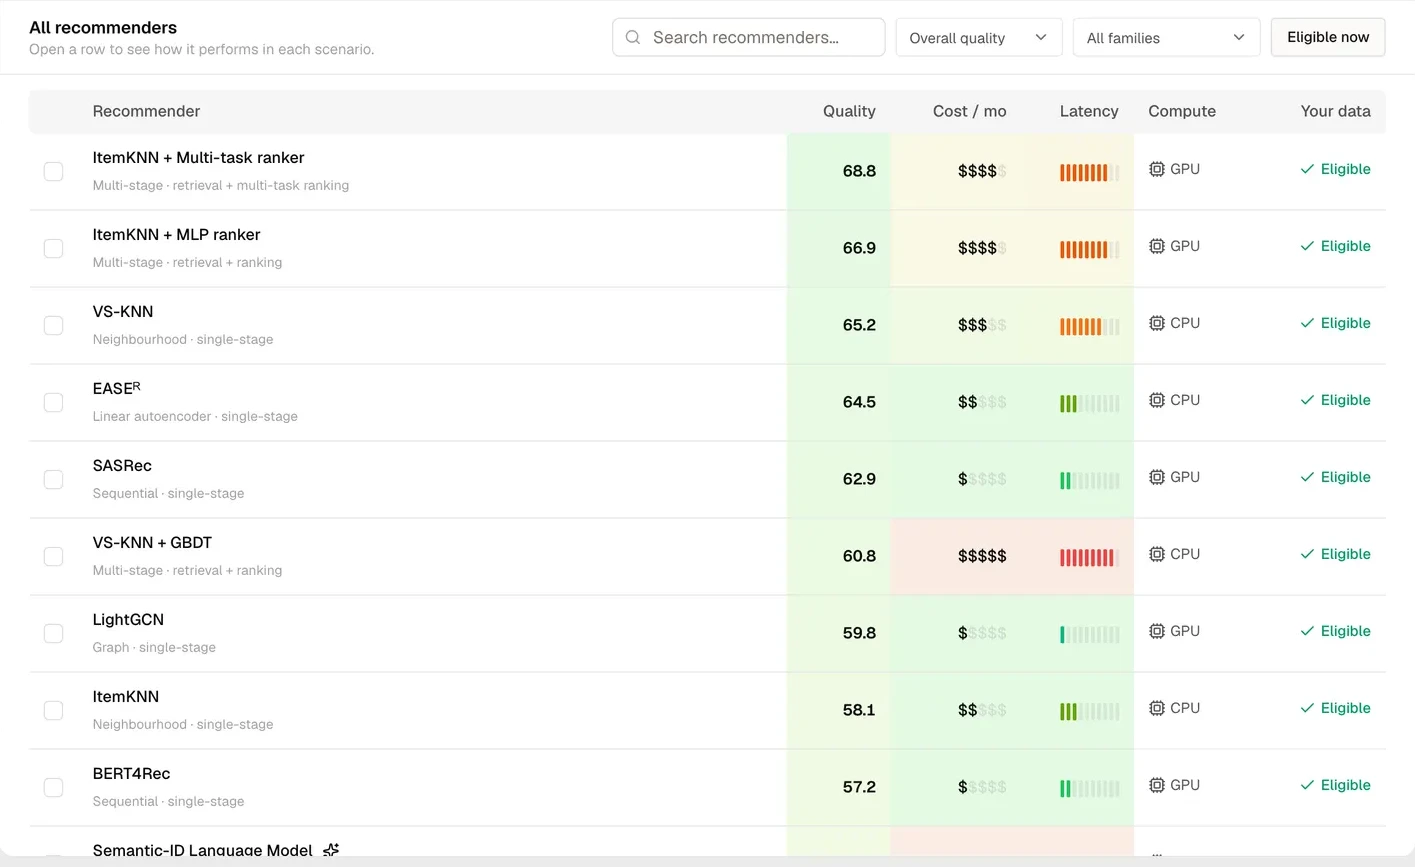
Collaborative, content-based, sequential, graph and generative recommenders trained on your actual behaviour, replayed over your history and evaluated the same way. The one that wins on your catalogue is the one that ships.
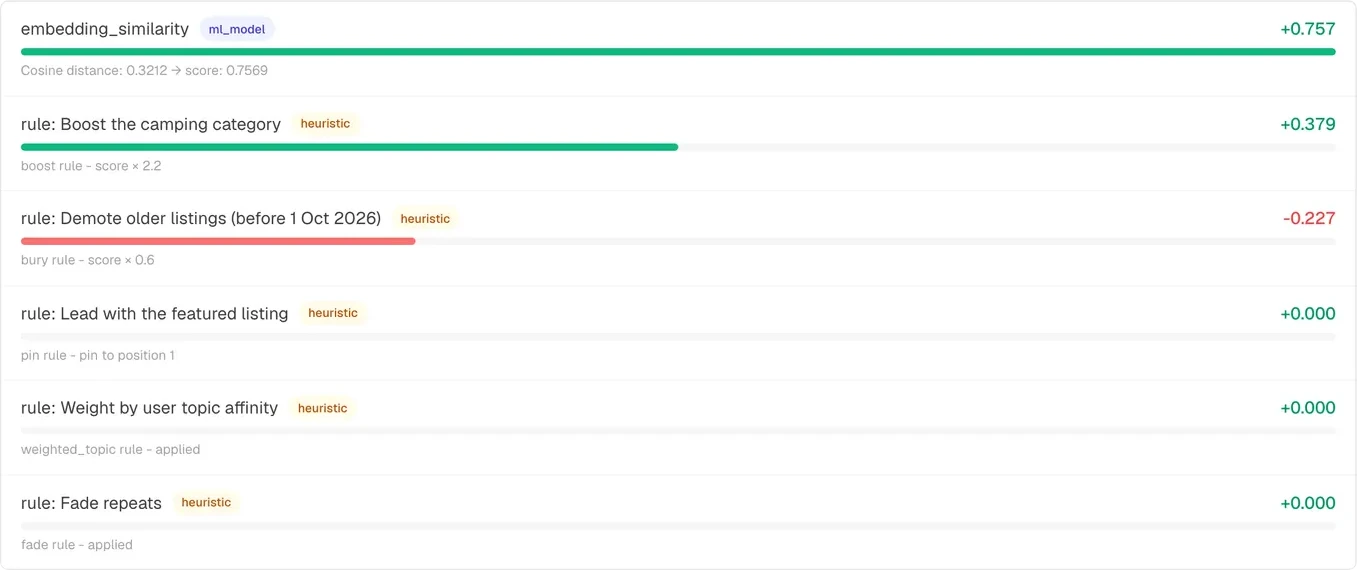
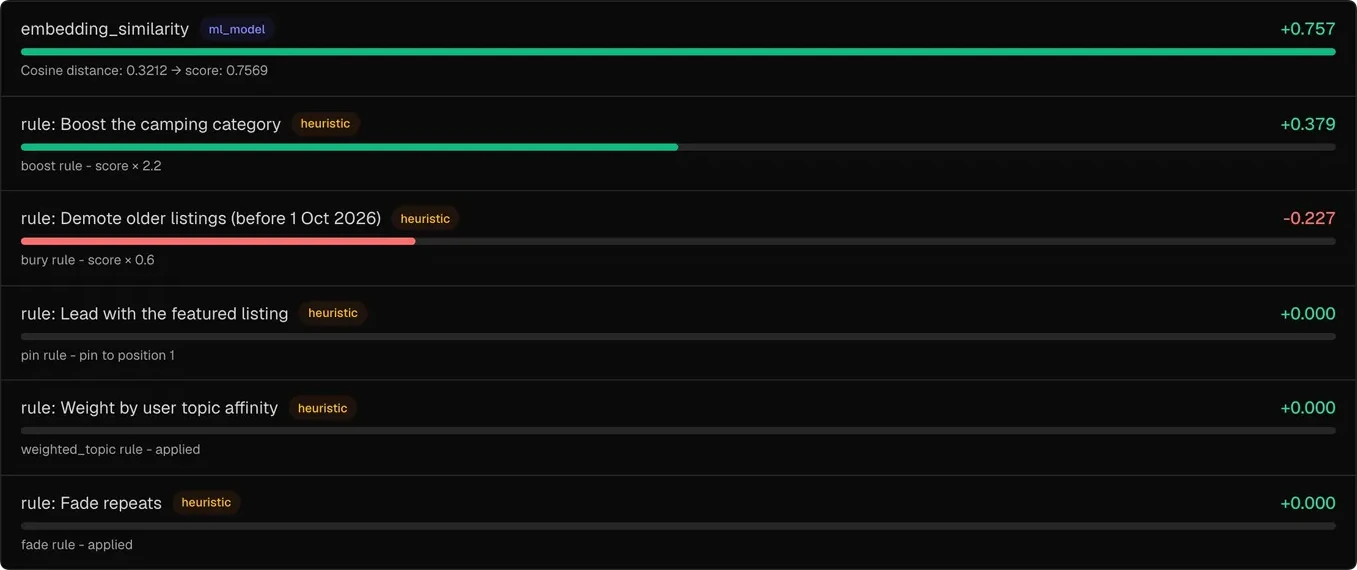
See why it happened
Any result traced back to the interests, signals and rules behind it, with confidence and model disagreement reported - alongside relevance, engagement, coverage, diversity, novelty, exposure, latency and cost.
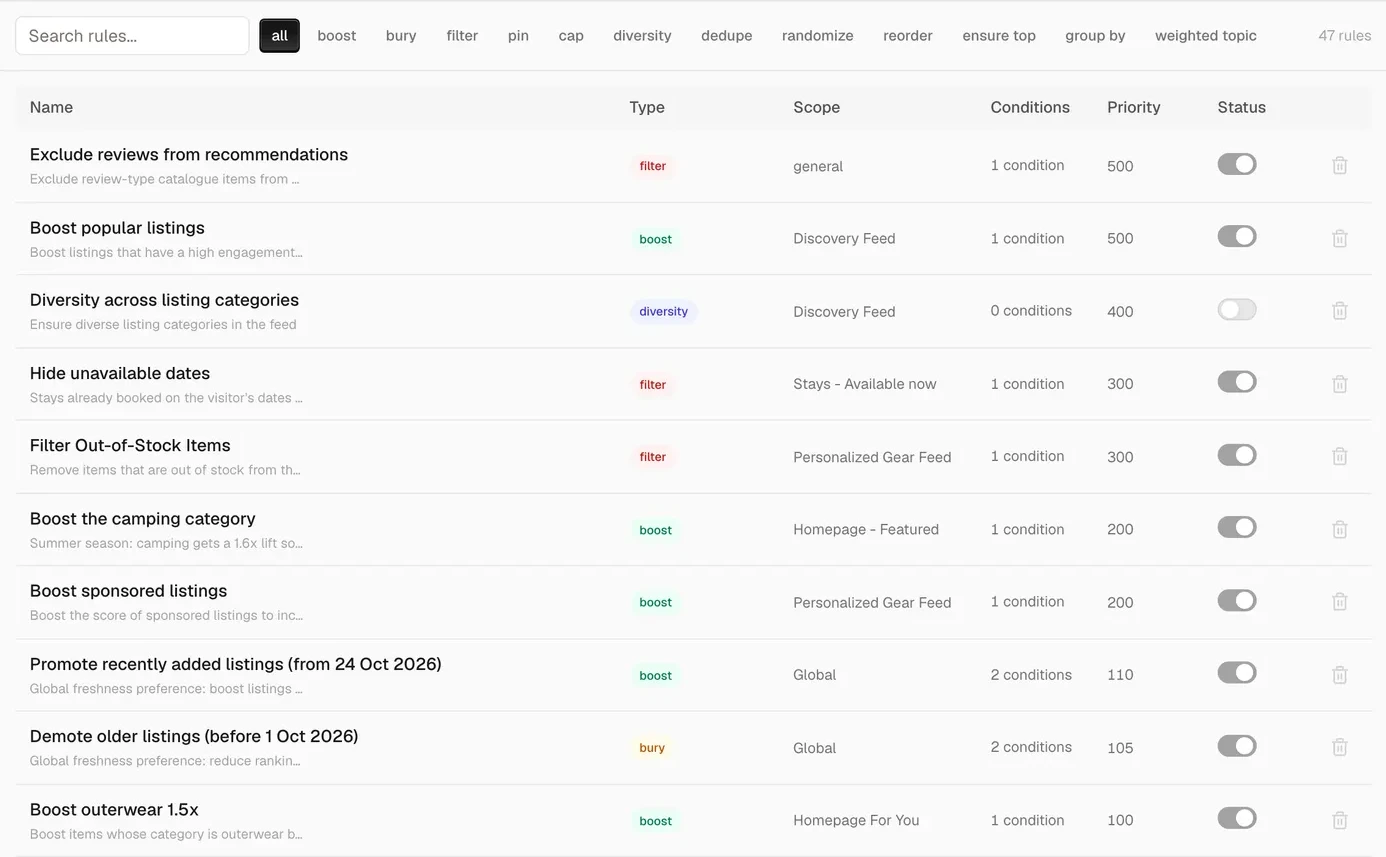
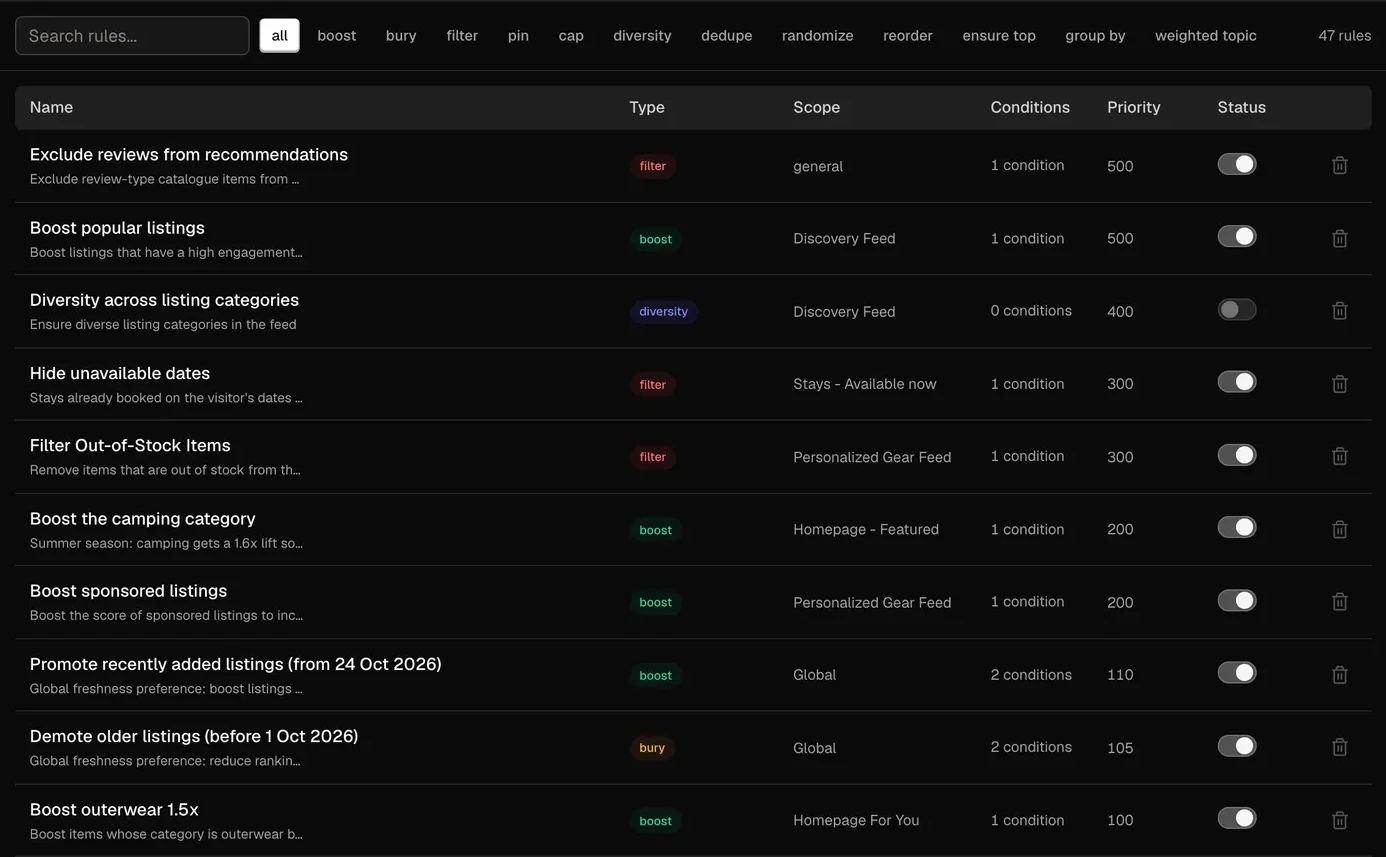
Control what gets shown
Boost, suppress, exclude, pin, guarantee or quota content per surface, at request time, and decide how hard an editorial call pushes against personalisation.
The console, environment by environment
01 · Audience
Map who you are talking to
Users, content, interests and behavioural clusters sit in one space you can explore rather than infer from a page of totals. The communities are found in the behaviour, not defined by hand in advance.
Communities nobody had to define
Groups that share interests or patterns surface on their own - including the ones starting to grow, before they are large enough to move a headline number.
Audience · communities
Found, not defined- Family car buyers182k+3%
estate, seven-seater
- Weekend breaks96k+1%
cottage, city flat
- Outdoor kit74k−2%
tents, bikes
- Home officeemerging21k+41%
standing desk, monitor
Nobody wrote a segment definition for any of these
02 · Profiles
Follow how interests move
Fragmented signals become one current picture of what a person wants now. Long-term preference and short-term intent are kept apart, so a single unusual session steers the visit without rewriting the profile behind it.
Intent and taste, kept apart
A timeline of the events that moved an interest, so a shift in someone's recommendations can be explained rather than guessed at.
Profile · u_41902
Updated 4s ago- Camping geartaste0.86
- Climbing and hikingtaste0.64
- Road bikessession0.58
- Kitchenwaretaste0.31
Why did this change?
saved · lst_7710 → road bikes +0.58
Session intent decays · established taste does not
03 · Content
Read the content itself
Multimodal embeddings let ranking work from photos, video, narration, objects, condition and setting instead of titles and tags. TwelveLabs' Marengo covers video, audio, image, text and document; OpenAI or your own models attach the same way.
Bring your own embeddings
Changing provider is configuration, not migration - and because relevance can be judged from the content, a new item is rankable the day it is published.
Content · embeddings
4 sources- TwelveLabs · Marengovideo, audio, image184k
- TwelveLabs · Marengotext, document62k
- OpenAItext9k
- Your own modeltext-
Photos, video and objects · not titles and tags
04 · Models
Test every architecture
Collaborative, content-based, sequential, graph-based and generative recommenders are trained on your actual behaviour, replayed over your history and measured against each other on the same footing, towards the outcome you chose rather than a generic proxy.
One API, whatever is underneath
Architectures, embedding providers and model versions can change without your application integration changing with them.
Models · this catalogue
Target: enquiries- Sequential · SASRec+6.1%0.92
- Graph · LightGCN+2.4%0.86
- Two-tower−0.8%0.81
- Generative slate−3.2%0.77
- Content-based−9.0%0.68
Same data, same evaluation · the comparison means something
05 · Releases
Promote only what wins
A candidate runs in shadow, then as a canary on a small share of traffic. It is promoted only once it beats the incumbent on the agreed metrics and stays inside your quality, diversity, latency and cost guardrails.
Automatic rollback
Live performance is watched throughout. A regression takes the release back out without anybody being paged for it.
Release · nsl-1-retail v5
Day 2 of 3- Shadow24h · answers, serves nothing
- Canary 5%homepage_rail · 41h in
- Canary 25%gated on day 3 guardrails
- Promoteautomatic once all pass
Relevance+4.8%Diversity−0.4%p95 latency41 msCost / 1k+2%Any gate fails and the release rolls itself back
06 · Explanations
Explain what came out
Every recommendation decomposes into the interests, interactions, content similarities and rules that produced it, with the rule that fired named alongside the signals. When a feed changes, the timeline says what changed it.
Uncertainty, reported
Confidence, data sparsity and disagreement between the candidate models are shown rather than flattened into one uniformly confident answer.
Why · item_8841
Rank 2 of 240- Interest · camping+0.41
- Content similarity+0.24
- Rule · new-season boost+0.12
- Catalogue popularity+0.09
- Recency decay−0.07
Candidates disagreesequential 2 · graph 9Confidence 0.81 · reported, not rounded away
07 · Control
Control what gets shown
Boost, suppress, exclude, pin, guarantee or quota content per surface, and set how hard an editorial decision pushes against personalisation. Rules apply at request time, so changing what surfaces needs no retrain and no redeploy.
Simulate before publishing
See how a boost, exclusion or quota would land for one person, for a segment, and for exposure across the catalogue - then preview any surface as any user.
Control · homepage_rail
4 rules- Ifstock = 0exclude
- Iftag = new-seasonboost ×1.4
- Ifcreator = in-houseguarantee 2
- Ifmargin < 8%suppress
Simulated catalogue exposure
- New season18% → 31%
- Back catalogue62% → 49%
- In-house20% → 20%
Nothing ships until the consequence has been looked at
Every capability
Read it in detail
Nine capabilities, grouped as the pitch runs. Open one for what it does, what it gets you, and where in the console it lives.
Understand your audience
Explore the relationships between your users, your content, their interests and the behavioural clusters they fall into.
Every user, item and interest sits in the same space, so the relationships between them can be looked at rather than inferred from a dashboard of totals.
Communities emerge from behaviour instead of being defined by hand, which surfaces the groups you did not know to look for alongside the ones you did.
- Behavioural clusters
- Groups of users who share interests or patterns are identified automatically, without anyone writing a segment definition first.
- Emerging interests
- Topics, products and content clusters that are starting to grow show up before they are large enough to move headline engagement.
- Catalogue coverage
- The same map reveals duplicate content, unusual clusters, missing metadata and the parts of the catalogue nothing reaches.
Follow how one person's interests move, and tell a settled taste apart from a single unusual session.
Fragmented behavioural signals are turned into one current picture of what a person is interested in now, rather than an average of everything they have ever done.
Long-term preference and short-term intent are held separately, so an unusual evening does not rewrite a profile - and a genuine change is still picked up quickly.
- A profile that stays current
- Interactions fold into the profile within seconds of arriving, so the next request already reflects the last one.
- Intent apart from taste
- Session-level intent steers the current visit; established preference survives it. Neither is allowed to drown out the other.
- Why did this change?
- A timeline of the events that moved an interest, a profile or a recommendation, so a shift can be explained rather than guessed at.
Understand your catalogue
Rank on what is actually in an item - photos, video, narration, objects, condition and setting - rather than on its title and tags.
Multimodal embeddings let ranking read the content itself. TwelveLabs' Marengo model covers video, audio, image, text and document embeddings; the same pipeline takes text embeddings from any provider.
Because relevance can be judged from the content, a new item can be placed the moment it is published, before it has accumulated any interaction history.
- Beyond titles and tags
- Two items with unrelated metadata but the same subject, tone or setting are recognised as related.
- Cold start, solved properly
- New and long-tail items are ranked on what they are, not on how many people have already clicked them.
- Find invisible content
- Good items that rarely get an impression, because the current system cannot confidently place them, are surfaced rather than left to sink.
Connect embeddings from TwelveLabs, OpenAI or your own internal models without rebuilding the recommendation layer.
Embeddings you already produce can be attached to items and used for retrieval and ranking straight away, alongside or instead of ours.
Changing provider is a configuration change rather than a migration: the ranking layer, the rules and the API you integrated against all stay where they are.
- Provider-agnostic
- TwelveLabs, OpenAI, an open-weights model you host, or a representation your own team trained - all attach the same way.
- Mix representations
- Different parts of a catalogue can carry different embeddings where that is genuinely the right answer.
- No lock-in at the vector layer
- Nothing about the integration assumes a particular embedding model, so replacing one does not cost you the rest of the system.
Test what works
Continuously test leading recommendation models against your data and deploy the one that performs best.
Collaborative, content-based, sequential, graph-based and generative architectures are trained on your actual behaviour and measured against each other on the same footing.
There is no single architecture that wins on every catalogue, so the platform's job is to find the one that wins on yours and keep checking that it still does.
- Candidates, measured consistently
- Every architecture is trained and evaluated the same way, so the comparison between them means something.
- Optimise for your outcome
- Train towards enquiries, bookings, retention, purchases or any custom event you define, rather than a fixed list of generic signals.
- One API underneath it all
- Architectures, embedding providers and model versions can change without touching your application integration.
- LLM judgement, bounded
- Cross-encoders or listwise LLM rerankers can reorder a bounded candidate set under a strict latency budget, with automatic fallback if the budget is missed - and your deterministic rules still applied afterwards.
A new model goes live only when it beats the current one, and comes back out automatically if live performance drops.
Promotion is conditional: a candidate has to beat the incumbent on the metrics you agreed and stay inside your quality, diversity, latency and cost guardrails.
Releases run in shadow first, then as a canary against a small share of traffic, with automatic rollback if the live numbers move the wrong way.
- Shadow mode
- A candidate answers real traffic without serving it, so it can be compared against the incumbent on the same requests.
- Canary and rollback
- A small percentage of traffic goes first. Live performance is watched, and a regression rolls the release back without anyone being paged.
- Guardrails, not just accuracy
- Diversity, coverage, latency and cost are release conditions in their own right - a model that wins on relevance alone does not ship.
Explain what happened
Trace a result back to what produced it, and read relevance, engagement, coverage, diversity, novelty, catalogue exposure, latency and cost across every model and every surface.
Any recommendation can be traced back to the interests, interactions, content similarities and business rules that produced it.
Exposure is measured as well as engagement: you can see how attention is distributed across genres, creators, products, providers and editorial categories.
- Why this was recommended
- A decomposition of a single result, with the rule that fired named alongside the interests, interactions and similarities that moved it.
- Replay the past
- Run a prospective model against historical user journeys to see how its recommendations would have differed.
- Know when it is uncertain
- Confidence, data sparsity and disagreement between the candidate models are reported rather than hidden behind a uniformly confident answer.
Control what gets shown
Boost, suppress, exclude, pin or guarantee content, and set how hard editorial decisions push against personalisation.
Contexts give each surface its own configuration, and rules are applied at request time - so changing what surfaces needs no retrain, no redeploy and no release.
You decide how strongly an editorial decision overrides the model, rather than choosing between a fully automated feed and a fully manual one.
- The control room
- Boosts, suppressions, exclusions, pins and guaranteed placements, each scoped to the surface it belongs to.
- Simulate before publishing
- Preview how a boost, exclusion or quota would land for individual users, for a segment, and for catalogue exposure overall.
- Preview as any user
- Pick a person and inspect exactly what they would be served on each surface right now.
Consent, retention and deletion rules applied throughout events, profiles, embeddings and trained models.
Consent state travels with the data it belongs to, so a person's preferences are honoured at ingestion, in their profile, in the embeddings derived from it and in the models trained on it.
Access is scoped by tenant and by role, with API keys and OAuth clients created, rotated and revoked from the console.
- Deletion that reaches the model
- A deletion request is not complete when the events are gone. Profiles and derived representations are covered by the same policy.
- Credential lifecycle
- Issue, rotate or revoke keys and OAuth clients instantly, scoped to the tenant they belong to.
- Role-aware teams
- Team members see the workspaces their role allows, and support access is separated from tenant data.
Ranking that works on behalf of catalogues
Can your recommender do this?
Not a different recommender - the layer above whichever one you run.
Content it can see
Photos, video, narration and objects read from the item itself, so a new one is rankable before it has a single view.
Model selection
Collaborative, content-based, sequential, graph and generative architectures trained on your behaviour and compared like for like, rather than one fixed model for every catalogue.
Safe releases
Shadow, then canary, then promotion - and automatic rollback the moment live performance drops.
Editorial control
Boost, suppress, pin or guarantee at request time, with the strength of the override set by you.
A traceable result
Every position decomposed into the interests, similarities and rules that produced it, with confidence attached and model disagreement shown.